New Deepseek, GLM 5.3, Grok 4.6, LTX 2.5, Qwen 3.8, Gemini 3.7: AI NEWS
Framework giving video models precise camera movement control from an input image plus a camera path. Code released under Apache 2, built on Wan 2.2.


Positional encoding method that gives video diffusion transformers precise camera control from an image and camera path.
Updated EU status checked Last shown
Sources: the vendor's own pages (linked above) and creator videos at the linked timestamps. EU status is information, not legal advice; see how we check.
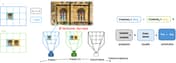
SCoPE (Sightline-Coordinate Positional Encoding) is a research method from Tencent-affiliated authors for adding camera control to pretrained video diffusion transformers. Each video token receives its camera ray, derived from the user's camera trajectory, as a second positional coordinate. Ray geometry inside attention helps resolve appearance ambiguity and makes generation follow the target trajectory.
It is applied as a lightweight Normalize–Gate–Inject retrofit that supports both metric and up-to-scale poses and preserves the pretrained RoPE bit-exactly. It adds under 0.1% parameters and is reported to improve controllability and video fidelity at 5B and 14B scales. Creator coverage describes it as built on Wan 2.2 with code released under Apache 2.0.
The project page shows multiple trajectories per scene, WASD-style camera-driven motion of a third-person subject, and results on real captures, in-the-wild footage and stylized artwork. It also reports revisit consistency (returning to a previously seen region keeps it anchored) as an emergent property of the coordinate system rather than an added memory mechanism. It is a research framework rather than a hosted product; the page provided no repository or weights links.
Watch the moment: the exact second top creators show it. Videos load only when you press play, via youtube-nocookie.com.
Framework giving video models precise camera movement control from an input image plus a camera path. Code released under Apache 2, built on Wan 2.2.

Playable first-person-shooter world model that takes a starting frame and controller actions and generates real-time responsive video. Trained on about 70,000 clips from seven FPS games; beats Matrix Game 3 and HunyuanWorld; about 30 GB, code and dataset released.
Closest neighbours by meaning, not just by category.
Model
Research method for multi-shot text-to-video with frame-accurate cuts, fades and camera moves, built on Wan2.1-T2V-14B.
Model · Tencent ARC Lab
Video world model from Tencent ARC Lab that turns an image or text into camera-controlled explorable scenes with 3D-aware memory.
Research · Preferred Networks
Generative method from Preferred Networks that reconstructs high-resolution 3D scene meshes from posed multi-view images.

Model · Tencent
Tencent's Qwen3-VL-based model unifying detection, pointing, OCR, segmentation and alpha matting in one VLM.

Research
Training-free, skeleton-free video motion transfer across subjects using TransPE on a frozen WAN-T2V diffusion transformer.

Model
3D-aware 360° video diffusion model that generates panoramic videos along user-defined camera paths from sparse panoramas.